Developer & Tech
How Do You Redact Sensitive PII Before Sending Data to Commercial LLMs?
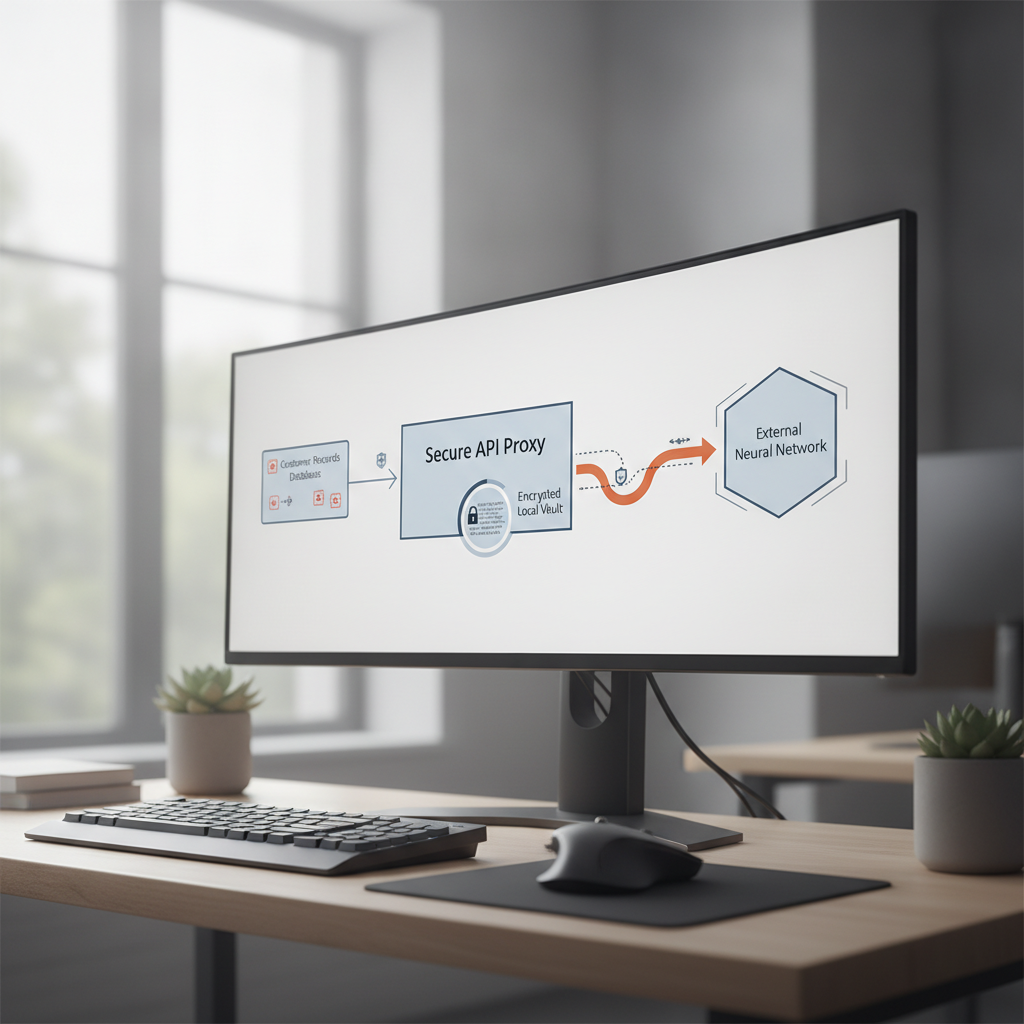
To redact sensitive personally identifiable information before sending data to commercial language models, you intercept outbound requests using an isolated pre-processing proxy. This proxy identifies entities via deterministic pattern matching and lightweight local named entity recognition, replaces them with reversible pseudonymous surrogate tokens stored in an in-memory vault, and reconstructs the original details inside the outbound response before returning text to users.
Sending unscrubbed enterprise data to third-party model providers invites severe regulatory fines, client contract breaches, and irreversible data leakage. Relying on the commercial frontier model itself to ignore or self-censor private records is ineffective because models process every token in the prompt payload. A robust sanitisation architecture treats redaction as a distinct, deterministic security boundary executed entirely inside your private infrastructure.
By Jim Vernon, Editor, AI Intelligence International · Published 12 October 2026 · Reviewed against our editorial standards · About the author
What are the key takeaways?
- Never ask a commercial model to self-redact private records because context injection still exposes raw customer data to third-party infrastructure.
- A hybrid sanitisation pipeline combining deterministic regular expressions with local small language models catches structured identifiers and unstructured context reliably.
- Reversible tokenisation preserves semantic utility for language tasks while keeping real personal data inside your local encryption boundary.
- Benchmarking latency and token inflation is essential because surrogate keys alter tokenisation efficiency and pipeline runtime.
What does this article cover?
| Question answered | How Do You Redact Sensitive PII Before Sending Data to Commercial LLMs? |
|---|---|
| Topic | Developer & Tech |
| Reading time | About 6 minutes (1,407 words) |
| Written by | Jim Vernon, Editor, AI Intelligence International |
| Published | 12 October 2026 |
| Last updated | 12 October 2026 |
Why is client-side PII redaction mandatory for commercial AI APIs?
Commercial model providers frequently log request payloads for monitoring, debugging, or policy compliance, even when their commercial terms promise not to train base weights on enterprise API traffic. If raw employee payroll data, patient case files, or customer credit card details sit inside your prompt context, you have transferred custodial control of sensitive assets to an external provider. Once ingested, this data exists in network transit logs, vendor cache tiers, and third-party observability clusters outside your control.
Data protection frameworks such as the UK General Data Protection Regulation and the European Union General Data Protection Regulation impose strict legal requirements on data residency, processing justification, and third-party transfers. When you transmit identifiable customer attributes across jurisdictional borders without strict user consent or processing guarantees, your company faces direct statutory liability. Scrubbing personal markers prior to external API dispatch transforms controlled personal records into non-identifiable context, dramatically lowering your governance exposure.
What is the difference between data masking and reversible tokenisation?
Data masking permanently obscures personal identifiers by replacing them with generic tags like customer name or random redaction blocks. While masking works adequately for simple classification tasks, sentiment analysis, or bulk extraction, it destroys grammatical fluency and contextual relations. When an downstream model needs to process long conversational threads, replacing every individual name with a static identifier causes cross-referencing errors, pronouns confusion, and garbled contextual reasoning across complex multi-party exchanges.
Reversible tokenisation replaces sensitive values with unique, syntactically consistent surrogate identifiers, such as substituting an individual name with a specific placeholder like user_alpha_49. An encrypted lookup vault maintains the mapping between the real entity and the surrogate key within your local infrastructure. When the external model returns its completion containing the surrogate tokens, your egress proxy swaps the real data back into the text, delivering a complete answer to the end user without exposing private values externally.
How do you build a multi-layered redaction architecture?
A reliable redaction pipeline uses a multi-stage funnel combining high-speed deterministic pattern matching with local semantic classification. The first layer handles structured identifiers that follow rigid syntactic standards, including national insurance numbers, telephone numbers, credit cards, bank accounts, and postal codes. Deterministic regular expressions and mathematical checksum algorithms execute these verifications in less than two milliseconds per document, filtering out high-risk structured data before any natural language processing occurs.
The second layer handles unstructured entities such as names, physical locations, private medical terms, and employer details embedded within free-flowing sentences. A lightweight local model, such as a compact Transformer or an open-source named entity recognition model hosted on an internal container, evaluates the text to locate sensitive tokens in context. Operating this recognition layer inside your private virtual cloud ensures that contextual data analysis occurs entirely on your own servers without external data exposure.
How do you calculate the latency and cost of a local redaction proxy?
Running local redaction introduces fixed compute infrastructure costs and network latency that must be weighed against third-party API spend and security risk. Consider a mid-sized legal tech platform processing 100,000 customer intake records per month, where each document averages 600 words, roughly equating to 800 input tokens. A production pipeline routes every request through an internal scrubbing microservice before invoking a frontier model priced at two dollars per million input tokens.
Operating an internal sanitisation container on a dedicated cloud instance costs 120 dollars per month. Running regex matching and local named entity recognition adds an average of 45 milliseconds of internal latency per document. In terms of external API charges, 100,000 requests at 800 tokens equal 80,000,000 tokens monthly, generating an external inference cost of 160 dollars at two dollars per million tokens. The total operating cost equals 280 dollars per month (120 dollars instance plus 160 dollars inference), with an end-to-end latency penalty under 50 milliseconds, proving that complete on-premises sanitisation adds negligible cost to your engineering stack.
How do surrogate tokens affect downstream model reasoning and costs?
Surrogate keys can alter how commercial tokenisers break words down into subwords, which directly impacts prompt token volume and semantic understanding. Replacing a natural human name like John Smith with an artificial identifier like surrogate_entity_user_0093 splits a single word into multiple subword tokens. This fragmentation can modestly increase your API token counts while degrading the language model's ability to grasp gender, tone, or narrative continuity across long conversations.
To prevent token inflation and preserve reasoning accuracy, format surrogate tokens as realistic synthetic equivalents rather than synthetic code variables. For example, your local vault can replace a real user name with a randomly drawn common name from a local database, and replace an actual physical address with a fictional street name in the same geographic region. The external model processes the prompt with full stylistic naturalness and normal token lengths, while your ingress-egress proxy silently swaps the synthetic records back to real customer profiles.
How do you handle edge cases, hallucinations, and unredacted leaks?
Even robust machine learning models produce false negatives when handling unusual nicknames, colloquial phrasing, phonetic typos, or indirect identifying descriptions. An effective redaction system implements defensive egress filters that inspect the external model's output before returning text to client applications. If an outbound completion contains a customer email address or phone number that failed initial intake scrubbing, your egress security gateway blocks the response immediately and alerts your security team.
Maintain an automated validation harness containing historical customer interactions annotated with verified sensitive fields. Run daily integration tests against your redaction microservice to confirm that prompt modifications, library upgrades, or regex adjustments do not degrade precision or recall. Tracking false positives and false negatives over time lets your team systematically patch detection gaps without introducing unmonitored code changes into production environments.
What do people ask most about this?
Can I simply prompt the commercial model to ignore personal data?
Instructing a commercial model in system prompts to ignore, redact, or disregard private information is not an acceptable security control. Language models read the entire context window during inference, meaning that personal data is transmitted across the network and processed by third-party infrastructure regardless of output instructions. Prompt instructions can easily fail due to prompt injection attacks, unexpected user queries, or subtle edge cases, exposing raw private details in model completions or administrative logs.
How does PII redaction impact the accuracy of complex analytical tasks?
If you completely remove context using blank redaction markers, model analytical quality can decline significantly because syntactic structure and contextual relationships are lost. When you use reversible tokenisation with realistic synthetic placeholders, models retain complete grammatical structure, temporal sequencing, and narrative coherence. The commercial model reasons over the synthetic profiles without noticing any missing data, allowing downstream applications to generate accurate summaries, extraction tables, and draft responses without quality loss.
Where should the entity mapping vault be stored?
The entity mapping vault should reside exclusively inside your secure, isolated database tier, such as an encrypted Redis instance or an in-memory key-value store running inside a private virtual cloud. The vault must never be accessible from the public internet or co-located with third-party monitoring services. Sensitive mapping keys should be given a short time-to-live configuration matching the user session duration so that sensitive relationships are permanently wiped once request handling finishes.
What happens if a user submits personal information in an image or PDF?
When processing multi-modal inputs, you must run local optical character recognition and visual bounding box detection inside your own environment before sending raw visual assets to an external API. The text extracted by your OCR pipeline must route through your standard redaction service, while sensitive visual regions such as portrait photos, signatures, and account numbers must be blurred or blacked out locally before any image payload is dispatched externally.
How was this article researched?
This article is written and maintained by Jim Vernon, Editor at AI Intelligence International. Figures and claims are drawn from the calculators and models published on this site, from vendor documentation current at the time of writing, and from first-hand testing of the tools described. Every article is reviewed against our editorial standards before publication and re-checked whenever the underlying tools or pricing change.